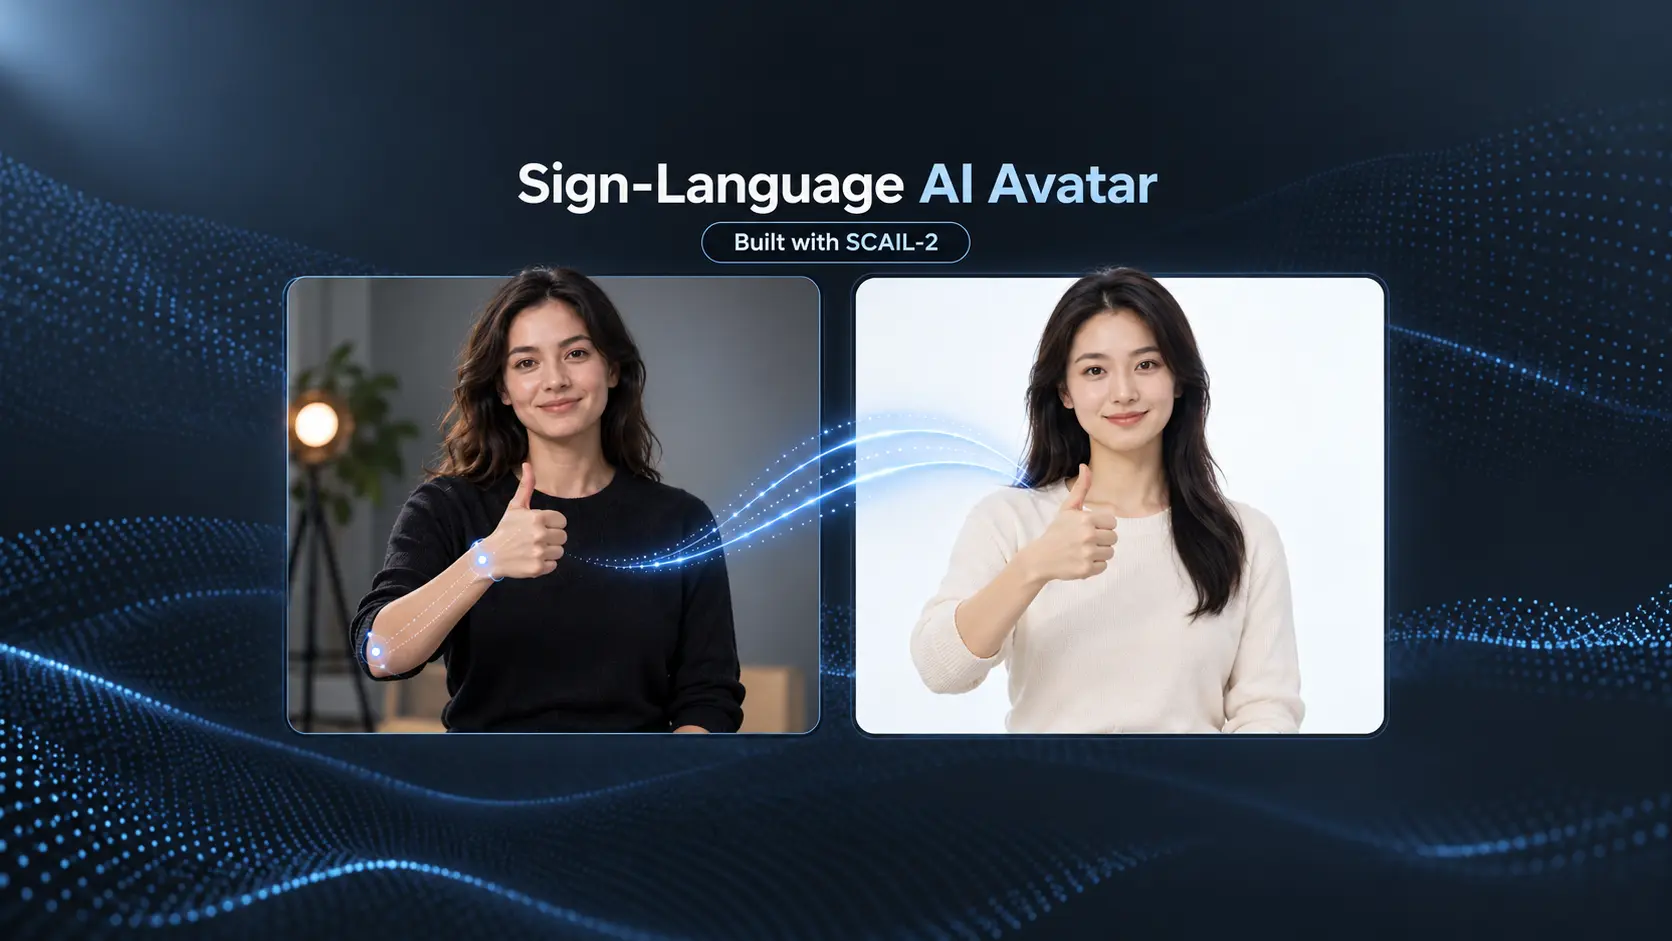
- We used SCAIL-2 to turn one reference photo into a consistent avatar that follows movements from real sign-language videos.
- Using ComfyUI and one RTX 4090, we created 27 videos at 720p in roughly 16–17 hours.
- Our automated pipeline prepares clips, generates and joins segments, cleans the background, and checks the output.
- Body and arm movements were reliable, but occasional finger errors required human review. Regenerating with a different seed fixed the thumbs-up error we found.
It works well for recorded, movement-focused videos, but sign-language accuracy still needs human verification before publishing.
Recording some sign-language videos is hard work. You’ll need a signer, a studio, good lighting, and a retake every time something changes. And if you want the same face in every video, the same person has to come back for every recording.
We wanted something simpler: record a signer once, and let an AI avatar perform the signs, looking the same in every video. In this post, we show how we did it with SCAIL-2, an open-source model that animates a photo with the movements from a video. We explain how it works, then walk you through running it yourself, step by step.
What We Built
Here is what the model produces. Both clips are its raw output, with no editing. The video was created from one reference image, and every motion comes from real signers' videos.
Demo 1: Look at how natural the arm movement is, and how stable the framing and the white background stay.
Demo 2: This clip was made in three pieces and joined. Watch the hands: the thumbs-up came out wrong on the first try, and we will show how we fixed it later in the post.
In total, we made 27 videos like these, at 720p, on one computer.
What Is SCAIL-2?
SCAIL-2 is an open-source character animation model. You give a reference photo of a person and a video of someone moving, and create a new video of the person in the photo making those same actions. It is built on Wan 2.1, which is a 14-billion-parameter video model, and it is free to download from Hugging Face.
Real-world analogy
Imagine a puppet and a puppeteer. The photo is the puppet; it decides the face, hair, and clothes. The signer is the puppeteer; they decide every action. SCAIL-2 watches the puppeteer and moves the puppet the same way, frame by frame, while the puppet keeps its own look.
How Does SCAIL-2 Work?
- Read the pose. SCAIL-2 finds the points of the body, arms, hands, and fingers in every frame of the driving video. Think of it as a moving stick figure.
- Read the look. An image encoder studies the reference photo, and a text encoder reads your prompt (for example, "plain white background").
- Draw the frames. Like AI image generators, it starts from random noise and cleans it up step by step until it becomes the avatar in that pose. A speed add-on (a LoRA) cuts this from 40 steps to 6.
- Work in pieces. It makes 81 frames (about 2.7 seconds) at a time. Each new piece starts from the last 5 frames of the previous one, so the joins stay smooth.
Why did we choose it for sign language?
We also tried Wan2.2-Animate. It is great at swapping a person into an existing scene, but it follows the arms and hands less closely. Sign language lives in the arms and hands, so SCAIL-2 was the better fit.

Walk away with actionable insights on AI adoption.
Limited seats available!

What Our Setup Looks Like?
Everything runs on a single NVIDIA RTX 4090. The main pieces are:
- ComfyUI: a free, node-based app for running AI image and video models. You can use it from a web page or control it from scripts.
- SCAIL-2 14B (fp8): the main model. fp8 is a compressed version that fits in 24 GB.
- Helper models: a text encoder (UMT5), an image encoder (CLIP Vision), a VAE that packs and unpacks frames, and SAM 3.1, which finds the person so the background can be made pure white.
- Two LoRAs: small add-ons, one for speed (lightx2v) and one for quality (DPO).
- Our scripts: a few Python files that prepare each clip, send the jobs to ComfyUI, join the pieces, and check the result.
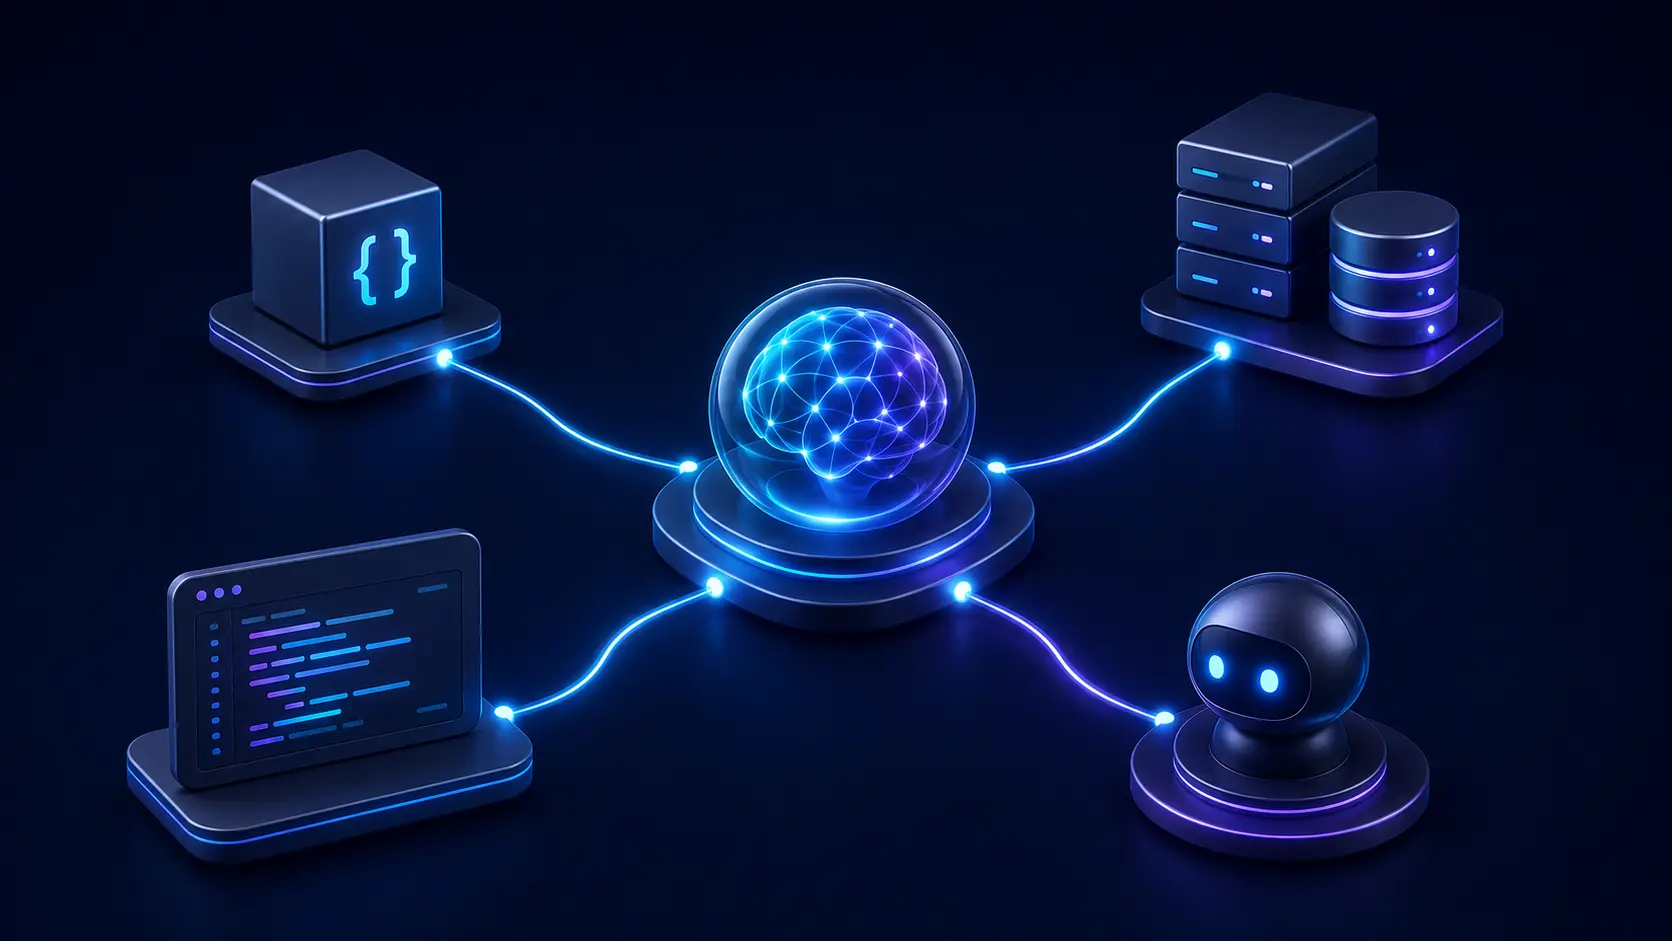
Here is how the pieces fit together, from the inputs at the top to the finished video at the bottom:

The setup at a glance · inputs, scripts, engine and models, outputs
How We Turned a Signer Clip Into an Avatar Video
Every clip goes through the same six steps. Our script runs them one after another, for every clip, without anyone watching.
- Prepare the clip. We find the signer, then centre and zoom the frame so the whole body, both elbows and both hands, fit in a 720×1280 portrait video. The reference photo is lined up with the signer's position.
- Write the prompt. One fixed description is used for every clip: the avatar's hair, clothes, and expression, a plain white background, and "no intro".
- Generate piece by piece. Each 2.7-second piece is a separate job, and it is saved to disk as soon as it is done.
- Join and trim. The pieces are joined and cut to the exact length of the original clip. We also drop the first few frames, where the model likes to add a "reveal" effect.
- Clean the background. SAM 3.1 finds the avatar in every frame and paints everything else pure white.
- Check the result. The script checks the length, that the body stays inside the frame, the white background, and roughly the hand positions. If a check fails, it makes the clip again with a new seed.
How long does it take? About 6 minutes per piece. A short clip is ready in 20 to 25 minutes, and all 27 clips took about 16 to 17 hours overnight.
How to Run SCAIL-2 Yourself
You can reproduce this with free tools. All you need is ComfyUI, seven model files, and the SCAIL-2 workflow that comes with ComfyUI. Setup takes about an hour, mostly spent downloading.
What you need: an NVIDIA graphics card with 24 GB of memory (such as an RTX 4090), about 64 GB of RAM, 40 GB of free disk space, and Linux or Windows with Python 3.12 and git.
Step 1: Install ComfyUI
git clone https://github.com/comfyanonymous/ComfyUI.git
cd ComfyUI
python3 -m venv .venv
source .venv/bin/activate
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu130
pip install -r requirements.txt
This downloads ComfyUI, creates a private Python environment for it, and installs PyTorch with NVIDIA support. On Windows, activate the environment with .venv\Scripts\activate instead.
Step 2: Download the models
Run this from inside the ComfyUI folder. Each file lands in the folder ComfyUI expects.
cd models
wget -P diffusion_models https://huggingface.co/Comfy-Org/SCAIL-2/resolve/main/diffusion_models/wan2.1_14B_SCAIL_2_fp8_scaled.safetensors
wget -P loras https://huggingface.co/Kijai/WanVideo_comfy/resolve/main/Lightx2v/lightx2v_I2V_14B_480p_cfg_step_distill_rank64_bf16.safetensors
wget -P loras https://huggingface.co/Comfy-Org/SCAIL-2/resolve/main/loras/wan2.1_SCAIL_2_DPO_lora_bf16.safetensors
wget -P vae https://huggingface.co/Kijai/WanVideo_comfy/resolve/main/Wan2_1_VAE_bf16.safetensors
wget -P text_encoders https://huggingface.co/Comfy-Org/Wan_2.1_ComfyUI_repackaged/resolve/main/split_files/text_encoders/umt5_xxl_fp8_e4m3fn_scaled.safetensors
wget -P clip_vision https://huggingface.co/Comfy-Org/Wan_2.1_ComfyUI_repackaged/resolve/main/split_files/clip_vision/clip_vision_h.safetensors
wget -P checkpoints https://huggingface.co/Comfy-Org/sam3.1/resolve/main/checkpoints/sam3.1_multiplex_fp16.safetensors
cd ..| Model | Job | Size |
SCAIL-2 14B (fp8) | Draws the avatar | 17 GB |
UMT5 text encoder | Reads the prompt | 6.3 GB |
SAM 3.1 | Finds the person | 1.7 GB |
DPO LoRA | Better quality | 1.2 GB |
CLIP Vision H | Reads the photo | 1.2 GB |
lightx2v LoRA | 6 steps instead of 40 | 0.7 GB |
Wan 2.1 VAE | Packs and unpacks frames | 0.2 GB |
Step 3: Start ComfyUI
python main.py
When the terminal prints To see the GUI go to: http://127.0.0.1:8188, open that address in your browser.
Step 4: Open the SCAIL-2 workflow
Go to Workflow → Browse Templates, search for SCAIL-2, and open SCAIL-2 14B character replacement (fp8). It is already wired to the seven files from Step 2.
Step 5: Add your photo, video, and prompt
- Load Video: your driving clip. Start with something under 5 seconds.
- Load Image: your avatar photo. A full-length photo on a plain white background, standing like the person in the video, works best.
- Prompt: describe the result, for example: "A young woman performs sign language, copying the driving motion exactly, with clear hand shapes. Plain white background, static camera, no intro."
- Mode: in both the Base and Extend parts, set replace_mode to false. This is Animation mode: the avatar moves on her own background, instead of being pasted into the original video.
- Size: for a portrait video, set width 512 and height 896.
Walk away with actionable insights on AI adoption.
Limited seats available!
Step 6: Press Run
Each 2.7-second piece takes about 6 minutes on an RTX 4090. The video appears in the Save Video node and in the ComfyUI/output folder.
For longer clips, add one more Extend part for about every 2.5 seconds of video: copy the Extend node, connect it after the last one, and raise its segment_index by one. To process many clips, you can send the same workflow to ComfyUI's API from a small script, which is what we did.
The Important Part: Getting the Hands Right
In sign language, one wrong finger can change the meaning. SCAIL-2 copies the body and arms very reliably, but now and then a hand shape comes out wrong. In Demo 2, the first version showed a pointing index finger where the signer made a thumbs-up.
What we tested
| What we tried | Result |
Raising the pose strength to 1.3 | No improvement: the same finger stayed wrong |
Full-quality mode (40 steps instead of 6) | About 13 times slower; not worth it for us |
Making the clip again with a new seed | Fixed: the thumbs-up came out right |
The errors turned out to be random. A seed is the number that sets the model's random starting point, so changing it gives a slightly different video, and usually a correct hand. In ComfyUI, open the Base and Extend parts, find SamplerCustom, change noise_seed (for example, from 1 to 2), and run again.
How we found the wrong signs
Watching 27 videos frame by frame is slow, so we wrote a small finger scan. It finds the hand points in the signer's video and in the avatar's video, and flags every moment where the fingers look different. It flagged 189 moments across all the videos. A person then checked each one: almost all were motion blur from fast movements, and only one was a real mistake, the thumbs-up in Demo 2. Our rule since then is simple: let the computer find the suspects, and let a person make the final call.
When Should You Use SCAIL-2?
SCAIL-2 is a good fit when:
- You want one consistent presenter across many videos, without recording that person each time.
- The movement matters most: sign language, dance, exercise demos, or gestures.
- You can run it on your own GPU, so the videos never leave your machine.
- You have time to review the hands before publishing.
It is a weaker fit for close-up faces and lip sync, for real-time use, or if you have no 24 GB graphics card.
Conclusion
With one open model, one graphics card, and a few scripts, a single recorded signer became a consistent avatar across 27 sign-language videos. SCAIL-2 handles the body and arms remarkably well, and the occasional wrong finger is easy to fix with a new seed. If you want to try it, start with one short clip and the six steps above, and watch your first avatar come to life.

Walk away with actionable insights on AI adoption.
Limited seats available!