Horizontal Scaling vs Vertical Scaling: Which Is Right for You?
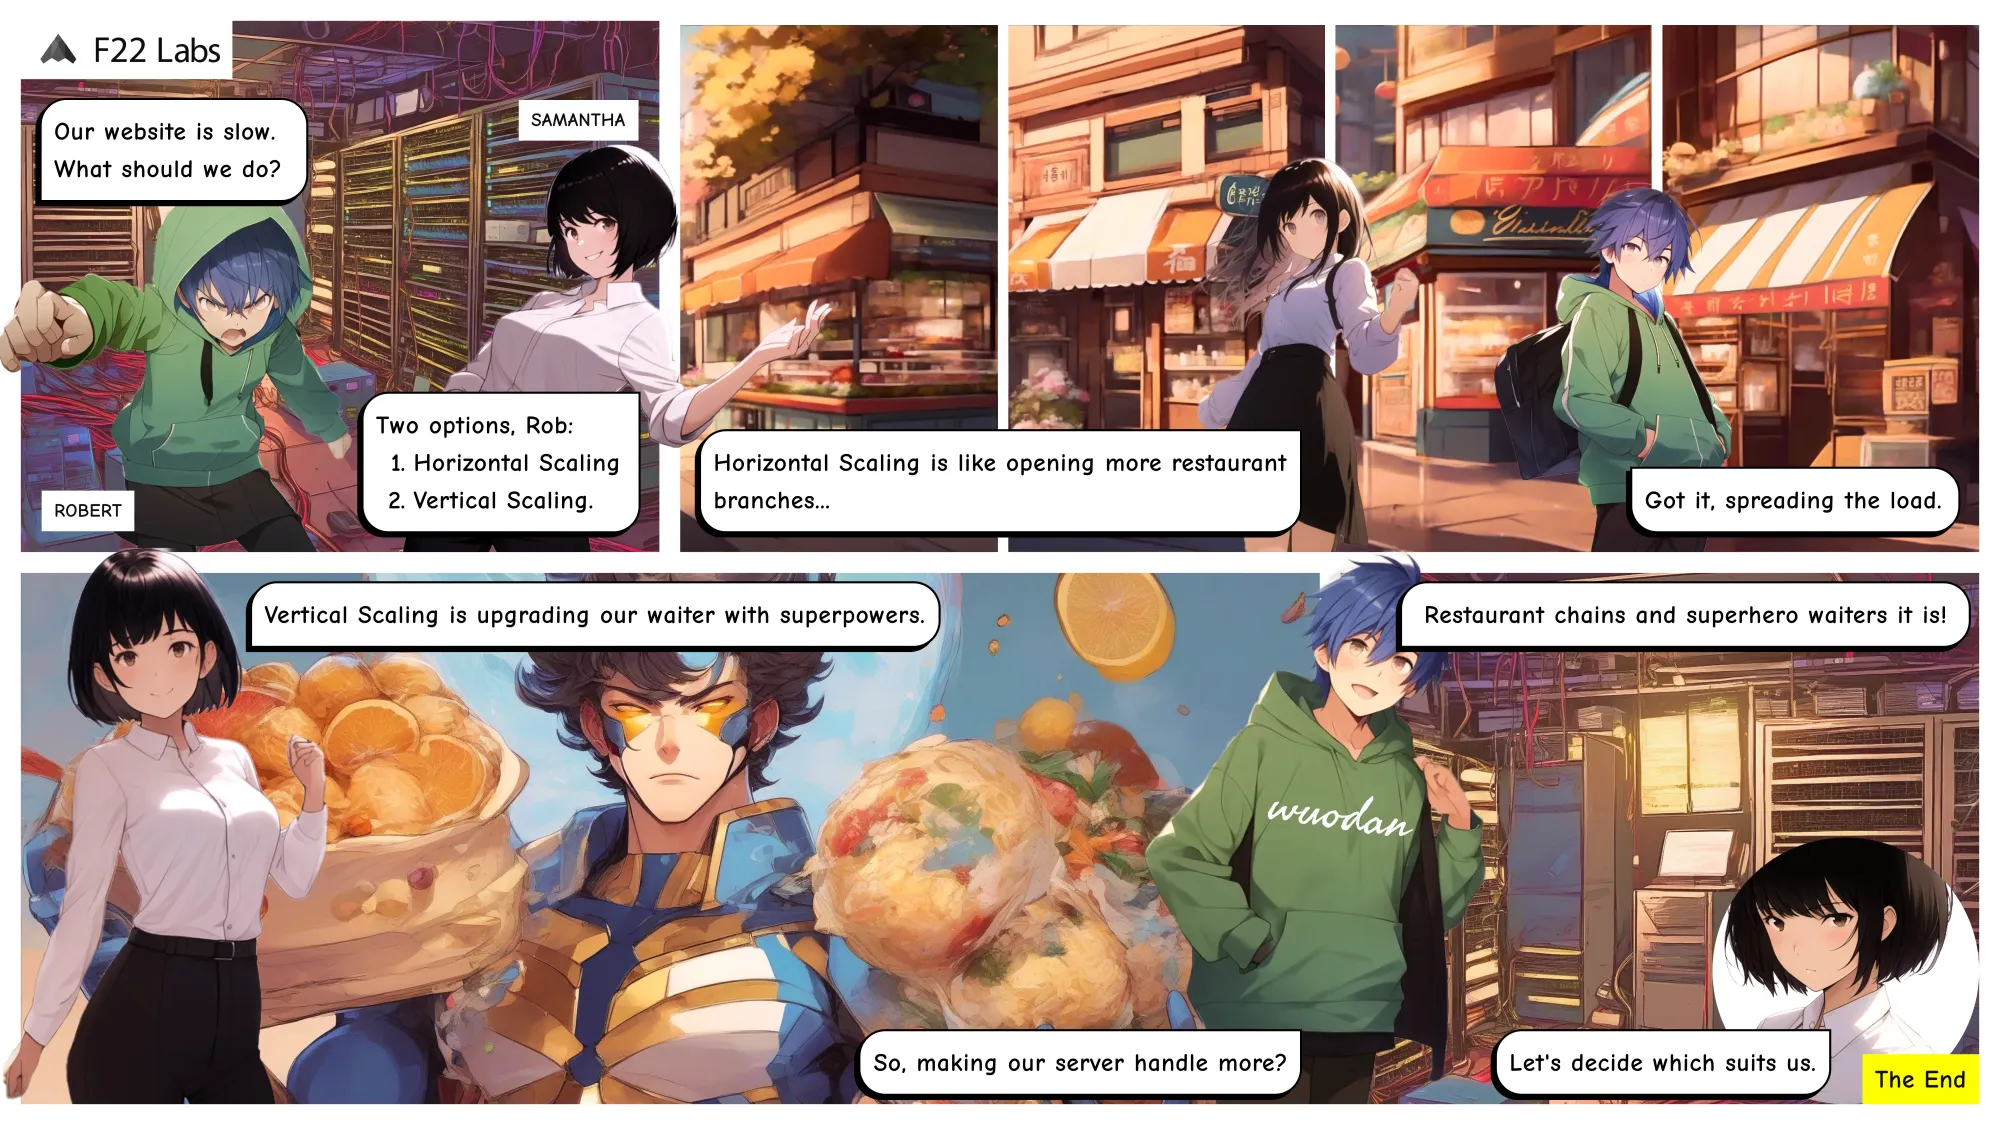
Scalability determines whether an application continues to perform as demand grows or begins to struggle under additional traffic, data, and background processing. The right scaling strategy can improve reliability and control infrastructure costs, while the wrong one may simply move the bottleneck somewhere else.
In our experience reviewing and building production systems, scaling problems rarely come from compute capacity alone. We have seen application servers receive more CPU and memory while performance remained almost unchanged because the real constraint was a slow database query, an exhausted connection pool, or a third-party API.
That experience leads to one essential rule: identify the bottleneck before choosing between horizontal and vertical scaling.
Horizontal Scaling vs Vertical Scaling at a Glance
Horizontal scaling means adding more machines or application instances. Vertical scaling means increasing the resources available to an existing machine.
| Factor | Horizontal Scaling | Vertical Scaling |
| Also known as | Scaling out or in | Scaling up or down |
| How capacity changes | Adds or removes instances | Adds or removes CPU, memory, storage, or GPU capacity |
| Typical architecture | Multiple servers behind a load balancer | One larger server |
| Capacity limit | Can grow across many instances | Limited by the largest available machine |
| Availability potential | Higher when instances span failure domains | Depends heavily on redundancy and failover |
| Application changes | Often requires stateless or distributed design | Usually requires fewer architectural changes |
| Operational complexity | Higher | Lower initially |
| Scaling speed | Well suited to automation | May require a restart or replacement |
| Common use cases | APIs, web applications, workers, streaming platforms | Databases, legacy applications, memory-heavy workloads |
| Cost model | Incremental but includes distributed-system overhead | Simple initially but larger machines can become expensive |
| Best long-term fit | Rapidly growing or variable workloads | Predictable workloads that fit on one machine |
The practical answer is often a combination: scale individual machines vertically until it becomes inefficient, then scale suitable components horizontally.
What Is Horizontal Scaling?
Horizontal scaling, or scaling out, increases capacity by adding more servers, virtual machines, containers, or application instances.
Consider an API running on one server. As traffic increases, you could run the same API on four servers and place a load balancer in front of them. Incoming requests would then be distributed across the available instances.
Kubernetes uses the same general model when its Horizontal Pod Autoscaler adjusts the number of workload replicas according to observed metrics. The Kubernetes documentation defines horizontal scaling as responding to increased load by deploying more Pods.
A typical horizontally scaled application contains:
- Multiple interchangeable application instances
- A load balancer or traffic router
- Health checks that identify unhealthy instances
- Shared or external storage for persistent data
- Centralized logging, metrics, and distributed tracing
- Automation for adding and removing capacity
Horizontal scaling works most naturally when each instance can process a request independently.
How Horizontal Scaling Works
Imagine an e-commerce application receiving 1,000 requests per second. One server can reliably process 300 requests per second, so additional servers are introduced behind a load balancer.
The load balancer sends each request to a healthy instance. Application data remains in a shared database, while session information may be stored in Redis or another external store. If an instance fails, the load balancer stops routing requests to it.
Adding servers increases aggregate capacity, but the improvement is rarely perfectly linear. Databases, shared caches, network bandwidth, locks, downstream services, and coordination between nodes can all limit the benefit.
AWS recommends replacing one large resource with multiple smaller resources when doing so reduces the effect of an individual failure. It also stresses that these resources should not share a common point of failure. That distinction matters because multiple instances alone do not guarantee availability.
Advantages of Horizontal Scaling
Greater capacity for parallel workloads
Horizontally scaled systems can process more concurrent requests by distributing them across multiple instances. APIs, background workers, web servers, image processors, and message consumers are common examples.
This approach is particularly effective when work can be divided into independent units. Ten workers can usually process ten unrelated jobs more effectively than one worker performing them sequentially.
Better availability
Multiple instances allow traffic to continue flowing when one instance becomes unhealthy. Instances can also be distributed across availability zones, data centres, or regions to reduce the effect of infrastructure failures.
High availability still requires deliberate design. Health checks, redundant load balancers, multi-zone deployment, database failover, and sufficient spare capacity all contribute to a resilient system.
Flexible capacity
Horizontal scaling allows teams to add capacity during busy periods and remove it when demand falls. Cloud autoscaling services make this useful for applications with seasonal, unpredictable, or event-driven traffic.
Autoscaling works best when scale-out and scale-in policies are designed together, safe minimum capacity is maintained, and the selected metric reflects real demand. Microsoft’s autoscaling guidance recommends using corresponding scale-out and scale-in rules instead of allowing capacity to move in only one direction.
Safer maintenance and deployments
A multi-instance service can be updated gradually. Rolling or blue-green deployments replace a portion of the running instances while the remaining ones continue serving users.
This capability can reduce deployment downtime, provided the application maintains compatibility between old and new versions during the rollout.
Independent component scaling
A distributed architecture allows each component to scale according to its workload. An application might add checkout instances during a sale while leaving the administration service unchanged.
Independent scaling can improve efficiency because teams do not need to enlarge the entire system when only one component is constrained.
Challenges of Horizontal Scaling
Application state
Local state is one of the first obstacles teams encounter when adding replicas. A user may log in through one instance and send the next request to another instance that has no record of the session.
In production investigations, we have seen this appear as intermittent logouts, disappearing shopping carts, or inconsistent user journeys. The underlying servers were healthy; the application simply assumed that every request would return to the same machine.
Shared session storage, stateless authentication, external object storage, and database-backed state provide more durable solutions. Sticky sessions can help during a transition, although they reduce traffic flexibility and should not become the only protection against improper state management.
Distributed-system complexity
More machines create more communication paths and more possible failure modes. Requests can time out, messages can arrive twice, nodes can disagree temporarily, and partial failures can leave a workflow in an uncertain state.
Reliable horizontally scaled systems often require idempotency, retries with backoff, timeouts, circuit breakers, queues, observability, and clearly defined consistency rules.
Downstream bottlenecks
Application replicas may scale successfully while every replica continues sending work to the same database. The database then receives more connections and queries, turning it into the next bottleneck.
One pattern we repeatedly see during performance reviews is an application tier with plenty of spare capacity waiting on a saturated database or external service. Adding another application instance in that situation increases cost without materially improving throughput.
Uneven workloads
Traffic is not always distributed evenly. Long-running requests, large customer accounts, hot cache keys, or popular database partitions can overload individual nodes even when average utilization looks healthy.
Load-balancing algorithms, partition design, queue depth, request duration, and per-tenant metrics should therefore be reviewed alongside average CPU utilization.
Higher operational overhead
A distributed system needs service discovery, centralized monitoring, deployment coordination, certificate management, network policies, and failure testing. Containers and orchestration platforms help manage this complexity, but they do not eliminate it.
Horizontal scaling becomes valuable when its availability or capacity benefits justify that additional operational responsibility.
What Is Vertical Scaling?
Vertical scaling, or scaling up, increases the capacity of an existing machine by giving it more CPU, memory, storage throughput, network bandwidth, or accelerator resources.
A database server with four virtual CPUs and 16 GB of memory might be moved to an instance with 16 virtual CPUs and 64 GB of memory. The application continues using one database endpoint, while the larger machine processes more work.
Let’s Build Scalable Cloud Solutions
We design smart infrastructure that supports your growth, from optimizing servers to building horizontally scalable architectures.
Vertical scaling is frequently the fastest response to a clearly measured resource constraint. It can create valuable breathing room while the team optimizes the application or prepares a longer-term architecture.
How Vertical Scaling Works
Vertical scaling changes the resources assigned to a workload rather than the number of workload instances.
In a physical environment, this could involve installing additional memory or replacing the processor. In the cloud, it usually means selecting a larger virtual machine or database tier.
Some platforms can adjust certain resources dynamically, while others must restart, replace, or migrate the machine. The maintenance implications should therefore be checked for the specific service instead of assuming that every resize is interruption-free.
Advantages of Vertical Scaling
Simpler architecture
A single larger machine usually requires fewer changes than converting an application into a distributed system. Existing code, local transactions, file access, and in-memory state may continue working as before.
This simplicity makes vertical scaling attractive for early-stage products, internal systems, and applications whose current workload remains well within the capacity of one machine.
Fast relief for measured constraints
Additional memory can reduce swapping and improve cache performance. More CPU can increase throughput for compute-bound workloads. Faster storage can improve database and indexing operations.
In our experience, a vertical upgrade is often the most practical immediate response when monitoring clearly shows CPU, memory, or I/O saturation. The upgrade buys time for investigation without forcing a rushed architectural rewrite.
Strong single-node performance
Some workloads cannot be divided efficiently across multiple machines. Large in-memory datasets, tightly coupled computations, certain commercial databases, and single-thread-dependent applications may benefit more from a stronger machine.
Network communication between nodes adds latency. Keeping closely related work on one machine can therefore produce better performance when the workload depends on frequent access to shared memory.
Lower initial operational complexity
One machine is generally easier to deploy, observe, back up, and troubleshoot than a cluster. Teams can focus on application behaviour without immediately introducing orchestration and distributed tracing.
This operational simplicity can be more valuable than theoretical scale for a small team or an application with predictable demand.
Compatibility with legacy applications
Legacy software may depend on local storage, process-level locks, machine-specific configuration, or commercial licensing. Rewriting these assumptions can be expensive and risky.
Vertical scaling allows such systems to handle more work while preserving the existing application model.
Challenges of Vertical Scaling
A fixed upper boundary
Every infrastructure provider has a largest available instance. Capacity growth eventually reaches that boundary, and each jump to a higher tier may become disproportionately expensive.
Vertical scaling should therefore be viewed as a finite path. A workload expected to exceed single-machine limits needs a plan for partitioning, replication, or architectural change.
Availability risks
One powerful machine can still fail. Production systems often pair vertical capacity with standby instances, replication, backups, and automated failover.
The presence of a standby also means that vertically scaled systems may still need traffic routing and synchronization. Vertical scaling simplifies the primary execution model, but it does not automatically remove the need for redundancy.
Possible downtime
Changing machine size may require a restart, replacement, or failover. The exact behaviour varies by cloud provider and managed service.
A resize should be tested and scheduled with the same care as any other infrastructure change. Stateful workloads also need a verified recovery and rollback plan.
Expensive high-end resources
Large machines can offer excellent performance, but premium CPUs, high-memory instances, GPUs, and high-IOPS storage can become costly. Licensing based on cores or machine size may further affect the calculation.
Cost comparisons should include redundancy, idle capacity, engineering effort, data transfer, and operational tooling—not only the hourly price of an instance.
Horizontal Scaling vs Vertical Scaling: Detailed Comparison
Performance
Horizontal scaling improves aggregate throughput when work can run in parallel. Vertical scaling improves the capacity and often the latency of a single machine.
A stateless API serving thousands of independent requests is a strong horizontal-scaling candidate. A memory-intensive analytics process that needs one large address space may benefit more from vertical scaling.
Reliability
Horizontal scaling creates the foundation for higher availability because a workload can survive the loss of an instance. Reliability depends on distributing those instances across independent failure domains and ensuring that the database, queue, network, and load balancer are also resilient.
Vertical scaling can support reliable systems when combined with replication and failover. Its primary machine still represents a larger concentration of capacity, so recovery design becomes important.
Cost
Horizontal scaling can match variable demand by adding and removing capacity. It also introduces costs for load balancers, orchestration, monitoring, inter-service traffic, replicas, and engineering time.
Vertical scaling offers a straightforward cost model at smaller sizes. Larger machine tiers may become expensive, and a high-availability deployment may require a second large machine that remains partly idle.
Horizontal scaling is therefore not automatically cheaper. The economical choice depends on utilization, redundancy requirements, software licensing, traffic patterns, and operating complexity.
Speed of implementation
Vertical scaling is usually faster when the current platform supports a larger machine and the workload can tolerate the resize process.
Horizontal scaling takes more preparation because the application must behave correctly across replicas. Once that foundation exists, automated scaling can respond more flexibly to changing demand.
Long-term growth
Horizontal scaling provides a broader path for applications expected to serve rapidly increasing or unpredictable traffic.
Vertical scaling remains suitable when demand is predictable, the workload needs strong single-node performance, or the expected capacity fits comfortably within available machine sizes.
Scaling Stateful Applications and Databases
Stateful systems require a more careful strategy than stateless application servers. Data must remain correct while requests are distributed across replicas, failures occur, and nodes change.
A relational database commonly begins with vertical scaling because increasing memory, CPU, and storage performance is simpler than partitioning the data. Read replicas can later distribute read traffic, while caching can remove repeated queries from the primary database.
Sharding or partitioning may become appropriate when writes, storage, or data locality exceed the capabilities of one database server. This change adds routing, rebalancing, cross-shard query, and transaction complexity, so it should follow measured need rather than architectural fashion.
Many production databases use both strategies. The primary and replicas are vertically sized for their workloads, while replicas or shards provide horizontal capacity.
The Hybrid Approach: Using Both Strategies
Most mature systems combine horizontal and vertical scaling rather than choosing one permanently.
An e-commerce platform might use:
- Horizontally scaled web and API instances for customer traffic
- Vertically scaled database nodes with read replicas
- Horizontally scaled workers for order processing
- A vertically sized cache that later becomes a clustered cache
- Object storage and a CDN for product images
- Independently scaled search infrastructure
This arrangement allows each component to use the strategy that matches its behaviour.
A practical growth path often begins with a well-structured application on one machine. The team scales that machine vertically while demand remains manageable, then moves sessions and files out of local storage. Application instances can then scale horizontally behind a load balancer. Databases, queues, caches, and other dependencies evolve independently as their own limits become visible.
First-Hand Lessons From Scaling Production Systems
The bottleneck decides the strategy
Architecture diagrams can suggest where scaling should happen, but production metrics reveal where it is actually needed. CPU saturation, memory pressure, queue depth, database latency, connection utilization, disk IOPS, and downstream response times tell different stories.
We have seen additional application replicas produce almost no improvement because each request was blocked by the same inefficient query. Optimizing the query delivered more capacity than adding servers would have.
Statelessness must be verified
Applications are often described as stateless even while storing sessions, temporary files, scheduled jobs, or rate-limit counters in local memory.
Traffic distributed across replicas exposes these assumptions quickly. Testing repeated requests against different instances before production rollout helps reveal hidden state.
Scaling moves bottlenecks
A successful scale-out operation can increase pressure on the database. A database upgrade can expose an application lock. Faster workers can overwhelm a third-party API.
Capacity testing should therefore measure the complete user journey rather than one isolated service. The goal is to understand where the next constraint will appear.
Autoscaling needs time and headroom
New machines or containers take time to start, pass health checks, warm caches, and receive traffic. A scaling policy triggered only after the service is fully saturated may respond too late.
Let’s Build Scalable Cloud Solutions
We design smart infrastructure that supports your growth, from optimizing servers to building horizontally scalable architectures.
Effective autoscaling keeps safe baseline capacity, uses early indicators such as queue depth or request concurrency, and accounts for startup time. Predictive or scheduled scaling can also help with known events.
Vertical scaling can be a strategic step
A larger machine is sometimes dismissed as a temporary shortcut, but it can be the right engineering decision. A vertical upgrade can stabilize a system quickly and create time for careful optimization.
The important distinction is whether the team understands the machine’s next limit and has a plan before reaching it.
How to Choose the Right Scaling Strategy
Begin by measuring the current workload. Identify whether the constraint is CPU, memory, storage, database performance, connection count, network bandwidth, queue capacity, or a downstream service.
Next, consider whether the work can run independently. Stateless requests and independent background jobs are natural candidates for horizontal scaling. Tightly coupled computations and applications dependent on local state may favour vertical scaling.
Availability requirements also shape the decision. Systems that must remain operational during machine failures need redundancy regardless of how much capacity one server provides.
Traffic behaviour matters as well. Predictable and gradual growth may be handled efficiently with vertical upgrades. Large, seasonal, or unpredictable changes are better suited to horizontal elasticity once the application supports it.
Team capability should remain part of the calculation. A distributed architecture introduces operational responsibilities that can slow a small team. A simpler system that meets current requirements is often more reliable than an elaborate platform the team cannot operate confidently.
Finally, compare the full cost of each approach. Infrastructure prices represent only part of the decision. Engineering time, monitoring, data transfer, licensing, standby capacity, deployment complexity, and incident response all contribute to total cost.
A Practical Scaling Process
A reliable scaling decision can follow this sequence:
- Establish a baseline for throughput, latency, errors, saturation, and cost.
- Reproduce expected and peak demand with realistic load tests.
- Identify the first constrained component.
- Remove avoidable waste, such as inefficient queries or unnecessary network calls.
- Apply vertical or horizontal scaling to the measured constraint.
- Repeat the load test and observe where the bottleneck moves.
- Test instance, zone, and dependency failures.
- Automate scaling only after the thresholds and recovery behaviour are understood.
- Review the strategy as traffic and architecture change.
This process prevents scaling from becoming guesswork.
Common Scaling Mistakes
Scaling before measuring
Resource utilization and end-to-end traces provide a stronger basis for decisions than assumptions. Optimization or configuration changes may solve the problem without additional infrastructure.
Treating replicas as automatic high availability
Several instances in one failure domain can still become unavailable together. Resilience requires independent placement, health-aware routing, data redundancy, and tested failover.
Leaving state on application instances
Sessions, uploaded files, and scheduled work stored locally can create inconsistent behaviour after scale-out. Shared state and idempotent processing make instances more interchangeable.
Ignoring databases and external services
Application capacity is useful only when dependencies can support the additional load. Connection pools, API quotas, queue throughput, and database locks should be included in capacity tests.
Using CPU as the only scaling metric
CPU is useful for compute-bound services, but queue depth, request concurrency, response latency, memory, and custom business metrics may predict overload more accurately.
Scaling every component together
Independent scaling prevents one busy feature from increasing the cost of the entire platform. Clear service boundaries and component-level metrics make targeted scaling possible.
Frequently Asked Questions
What is horizontal scaling?
Horizontal scaling increases capacity by adding more machines, containers, or application instances. A load balancer or queue distributes work among them, allowing the system to handle more concurrent traffic.
What is vertical scaling?
Vertical scaling increases the resources assigned to an existing machine. Common upgrades include additional CPU, memory, storage performance, network capacity, or GPUs.
Which is better: horizontal or vertical scaling?
The better option depends on the measured bottleneck. Horizontal scaling suits parallel, variable, and highly available workloads, while vertical scaling suits simpler architectures and workloads requiring strong single-node performance.
When should I use horizontal scaling?
Horizontal scaling is appropriate when workloads can run independently, traffic varies significantly, individual machine limits are approaching, or the service needs to tolerate instance failures.
When should I use vertical scaling?
Vertical scaling is useful when a larger machine can resolve the current constraint, the application is difficult to distribute, or operational simplicity is more valuable than near-unlimited expansion.
Is horizontal scaling cheaper than vertical scaling?
Horizontal scaling can be cost-effective for variable demand, but it is not always cheaper. Load balancers, replicas, orchestration, observability, data transfer, and engineering effort can increase its total cost.
Does horizontal scaling guarantee high availability?
High availability requires multiple healthy instances across independent failure domains, resilient dependencies, sufficient spare capacity, and tested failover. Adding replicas is only one part of that design.
Can databases scale horizontally?
Databases can scale horizontally through read replicas, partitioning, or sharding. These approaches add data-routing and consistency complexity, so many teams vertically scale the primary database before distributing it.
Can horizontal and vertical scaling be used together?
Yes. Many production systems vertically size individual nodes and horizontally scale the number of application instances, workers, database replicas, or shards.
Is autoscaling the same as horizontal scaling?
Autoscaling is automation that adjusts capacity according to metrics or schedules. It can change the number of instances horizontally or, on supported platforms, adjust resource allocations vertically.
Conclusion
Horizontal scaling is the stronger long-term choice for workloads that can run across interchangeable instances, need flexible capacity, or require resilience against individual machine failures. Vertical scaling is the simpler choice when a workload benefits from stronger single-node performance and remains within practical machine limits.
Most systems benefit from a hybrid strategy. Vertical scaling can provide immediate capacity, while horizontal scaling offers elasticity and broader growth once the application is ready for distributed operation.
The most reliable decision begins with evidence. Measure the bottleneck, choose the smallest effective change, test the result, and scale each part of the system according to its actual behaviour.